AI
Retrieval assistant over a document set
A LangChain assistant that answers from supplied documents rather than memory, served through an API and a chat front end.
Own buildTeam build
01The problem
What it had to solve.
A general-purpose chatbot asked about your own documents answers confidently and wrongly. Grounding it in a specific corpus is the difference between a demo and something staff can rely on.
02The build
How it was put together.
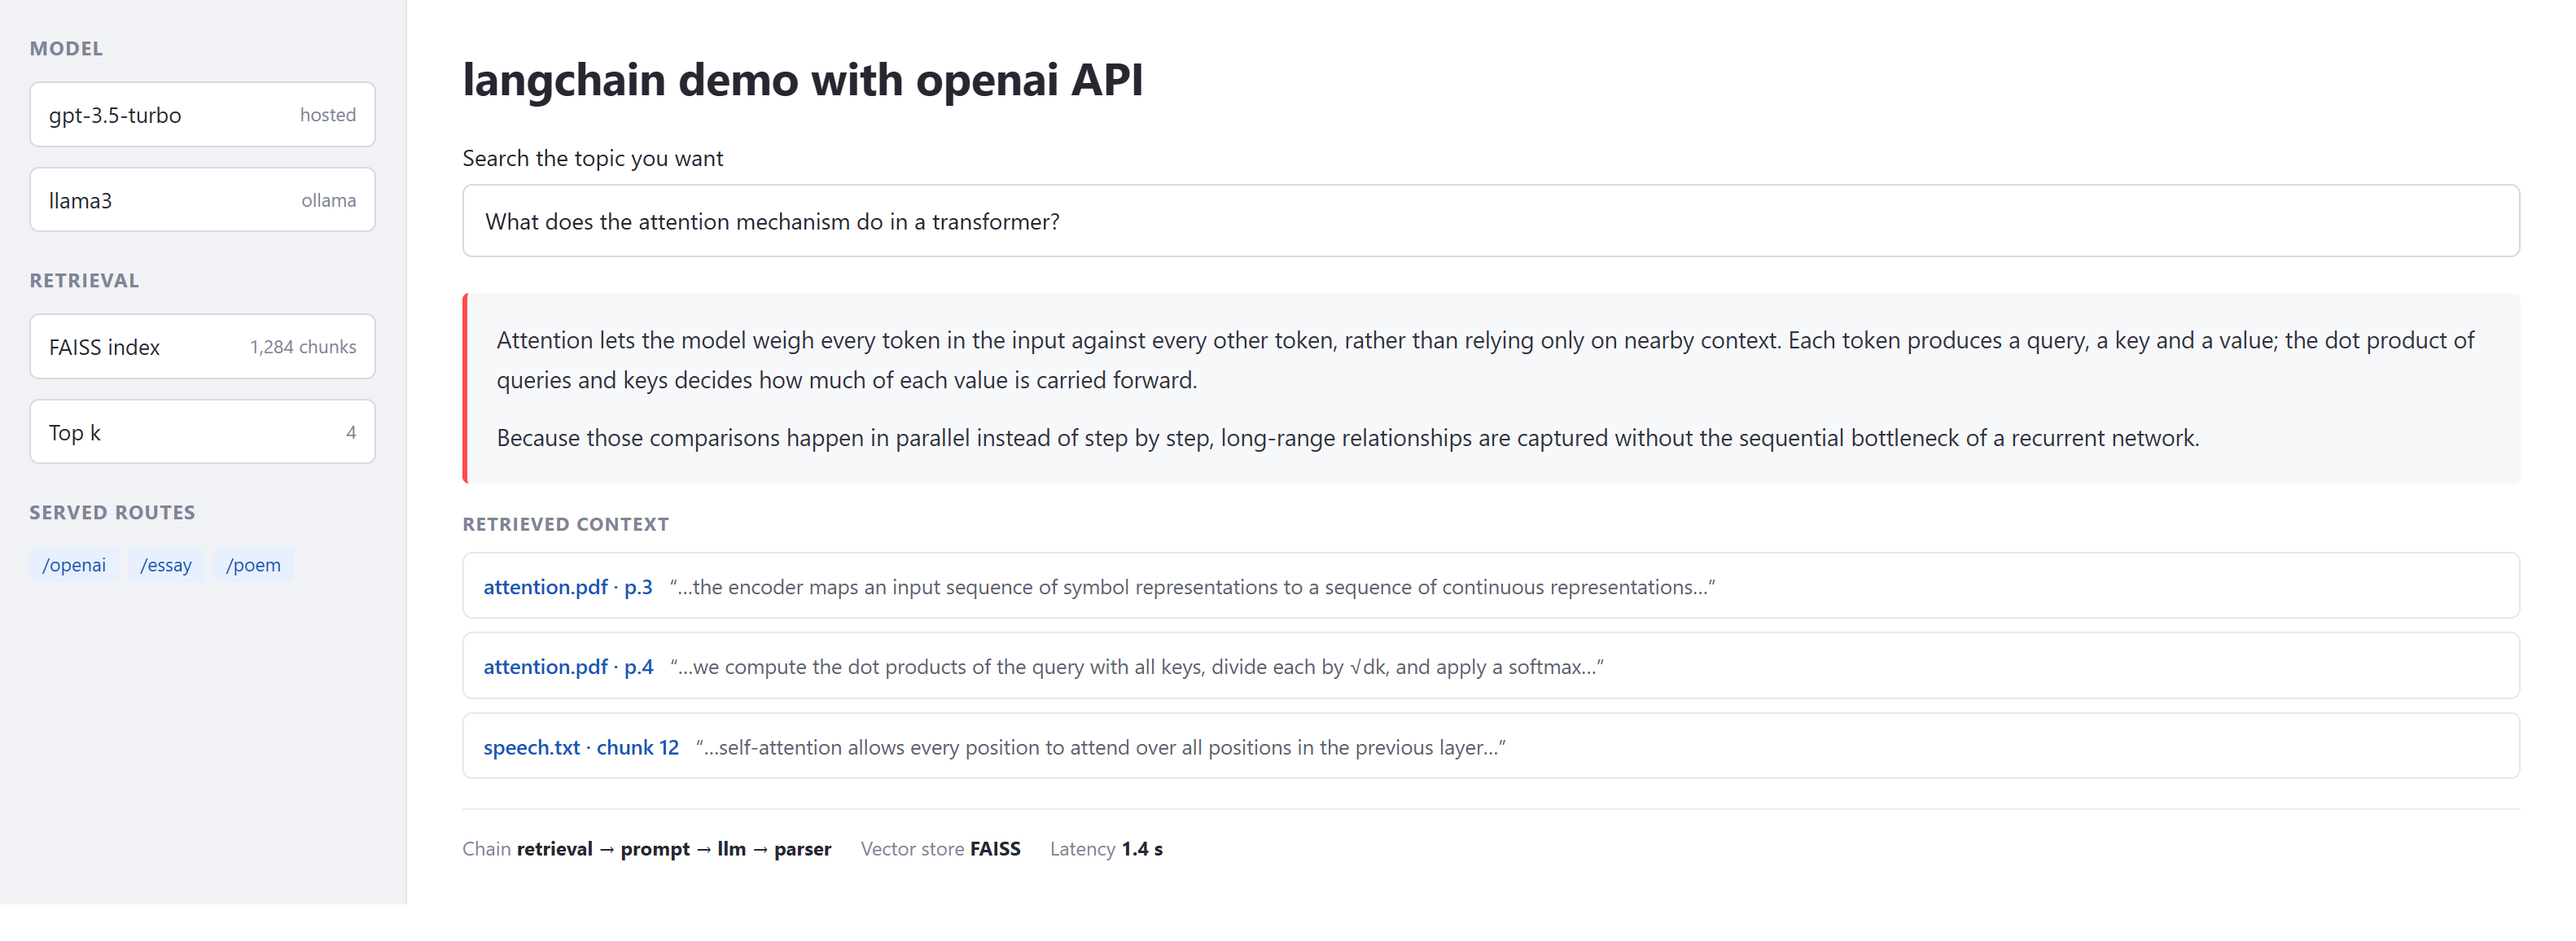
- Document loading and chunking across PDF and web sources, embedded into a FAISS vector index
- Retrieval chains passing the matched passages to the model as context, so answers come from the corpus
- Agent setup able to reach external tools — Wikipedia and arXiv retrievers — where the corpus does not hold the answer
- Served two ways: a LangServe API for other systems, and a Streamlit interface for people
- Model layer kept swappable between hosted APIs and a local Ollama runtime
Stack
LangChainPythonFAISSFastAPILangServeStreamlit
What it demonstrates
- Retrieval-augmented generation wired end to end, not just prompt engineering
- A model layer that can move between hosted and self-hosted without rewriting the app
- The same capability exposed to both humans and machines
Next step
Tell us what you are trying to build.
A first call is thirty minutes, costs nothing, and ends with a straight answer about whether we are the right group for it — plus the names of the specialists who would actually do the work.